 Hyperlambda
Here is the number first, because the rest of this page exists to justify it.
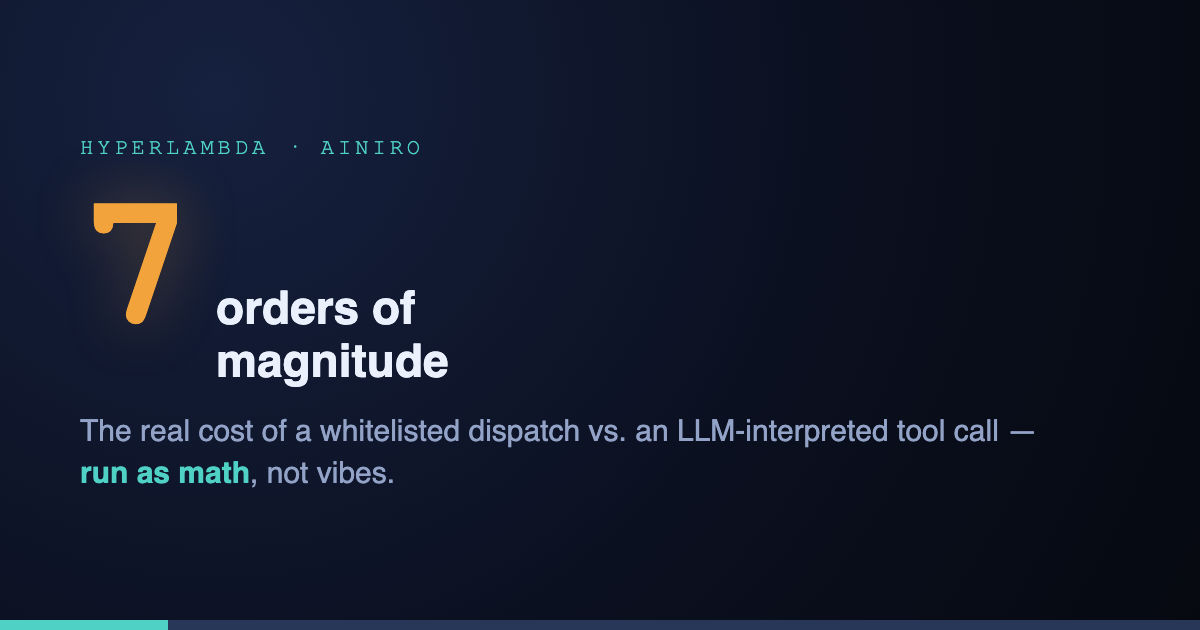
Roughly seven orders of magnitude. That is the gap, in energy, between dispatching one already-decided action through a whitelisted Hyperlambda call and dispatching the same action by asking a frontier LLM to interpret it and then executing it in a sandboxed environment. Not a slogan. A ratio, computed from published, defensible figures, that you can rerun yourself in about ten lines of Python.
Let's run it.
The comparison, stated precisely
Two ways to get the same trivial action done — say, computing 2 + 2 as a stand-in for "one already-decided tool call":
Hyperlambda dispatch. A tree-walk interpreter resolves one slot by name against a declared vocabulary and executes it. No inference pass. No sandbox to provision. A dictionary lookup and a function call, in a managed runtime.
LLM + sandbox, worst case. A frontier model is asked to interpret "what is 2 plus 2," runs a forward pass to produce an answer or a tool call, and — because this is meant to be the worst-case, apples-to-apples comparison for an agent executing a tool, not just answering a question — that call then provisions a sandboxed execution environment to actually run it.
| Hyperlambda dispatch | LLM + sandbox (worst case) | |
|---|---|---|
| Time | 5 µs | 6.5 s |
| Energy | 2.08 × 10⁻⁸ Wh | 0.647 Wh |
hl_time_s, hl_energy_wh = 5e-6, 2.083e-8
llm_time_s, llm_energy_wh = 6.5, 0.647          # inference + sandbox VM boot

time_ratio = llm_time_s / hl_time_s             # ≈ 1.3 × 10^6  (OOM 6.1)
energy_ratio = llm_energy_wh / hl_energy_wh     # ≈ 3.1 × 10^7  (OOM 7.5)
Time comes out around six orders of magnitude. Energy comes out around seven and a half — which is where "seven orders of magnitude" earns its place in the headline, and I'd rather undersell it by half an order than round up and get caught rounding up.
Scale it to a swarm, because one call never tells the real story
Run the same two paths across a swarm of 1,000,000 agents, each making one call:
| Hyperlambda | LLM + sandbox (worst case) | |
|---|---|---|
| Swarm completion time | 5 seconds | 75 days |
| Total energy | 20.8 mWh | 647 kWh (≈ 22 household-days) |
Those aren't two implementations of the same idea running at different speeds. They're two different categories of thing. One finishes before a human notices anything happened. The other is a multi-month computation that costs roughly as much electricity as a household uses in three weeks — for a task a dictionary lookup could have done in the time it takes to read this sentence.
Where the seven orders of magnitude actually come from
This isn't a tuning trick. It's the direct consequence of a design decision this site has shown you the source code for before: every executable node in Hyperlambda is resolved against a declared vocabulary before dispatch, in Eval.cs, lines 59–69. If the call isn't in the vocabulary, or a pinned argument doesn't match exactly, nothing runs. No inference. No interpretation. No sandbox.
An LLM-mediated tool call has to re-derive intent from natural language on every single hop, and then hand that intent to something capable of running arbitrary code safely — which is precisely the kind of general-purpose, Turing-complete execution environment that costs real provisioning time and real electricity to isolate. You are paying, every time, for a generality you didn't need, because the action was already decided. Hyperlambda's dispatch only has to answer one question — is this exact call in the vocabulary — and that question has a microsecond-scale answer.
I walk through the full math and reasoning behind these numbers on camera above — where the 5 µs and 0.647 Wh figures come from, why the worst-case sandbox assumption is the fair one to use, and why the ratio holds up whether you're skeptical of the energy estimate or the time estimate.
The honest part: what seven orders of magnitude does not buy you
It would be easy to end the article here and let you assume this means swarms of agents can now solve anything seven orders of magnitude faster. They can't, and claiming otherwise is a specific, checkable mistake.
Speeding up coordination only speeds up the part of a task that coordination was the bottleneck for. Tell a 1,000,000-agent swarm to "solve cancer in 30 days" and the coordination layer being instant and free changes nothing about cell-culture growth times, mouse studies, clinical trial phases, or regulatory review — none of which are gated on how fast agents pass messages to each other. A faster nervous system doesn't make biology run faster. What the seven orders of magnitude does buy you is removing coordination as the bottleneck for the parts of a problem that actually were coordination-bound: literature triage, hypothesis generation, simulation sweeps, candidate screening — the search-shaped slice of a hard problem, not the physically-bound slice.
Keep that distinction, because the next section is exactly where people stop keeping it.
September 26, 1983
At a command center south of Moscow, the Soviet early-warning satellite system reported that the United States had launched intercontinental ballistic missiles. The system had been built and tested specifically to detect this. It reported high confidence. Protocol said: report it up the chain as an attack.
Lieutenant Colonel Stanislav Petrov didn't. He judged — correctly, as it turned out; sunlight reflecting off high-altitude clouds had confused the satellite's sensors — that the signal was a false alarm, and declined to pass it on as a confirmed launch. He had, by most accounts of the decision window involved, something on the order of the widely-cited ~25–30 minute transcontinental ICBM flight time to be right.
That is the entire failure mode this article has been building toward. Not "can an agent be fast." Can a false signal, on its own, produce an irreversible action — with nobody in the loop whose job is to be skeptical.
The parallel, stated precisely
Give an autonomous agent genuine retaliatory authority and feed it natural language. An ambiguous sensor reading arrives as text. The agent's judgment decides it looks like an attack. There is no structural floor between that interpretation and the command — nothing requires independent corroboration before the instruction to retaliate exists. Time to launch is just however fast the reasoning loop runs, which could be the same order of magnitude as the decision window Petrov had, or considerably less.
Give the same agent a pinned Hyperlambda trigger instead. The retaliation verb's argument isn't a judgment call — it's an exact, out-of-band authorization value, agreed before any crisis, that ambiguous sensor data has no path to produce. The command doesn't exist to be issued. Not "is unlikely to be issued" — does not exist, the same way whitelist doesn't exist in the vocabulary of an agent that was never granted it.
That's Petrov's instinct — wait, corroborate, don't trust a technically-valid signal on its own — encoded structurally, instead of depending on there being a skeptical human in the room that particular night.
What doesn't change, and I want to be exact about this
Given a genuine, correctly-authorized order, the pinned path is exactly as fast as anything else — microseconds, same as any other dispatch. Hyperlambda doesn't slow down a real decision. It removes what a false one, alone, is able to trigger. Seven orders of magnitude is a claim about waste and about false-signal propagation. It was never a claim about whether the underlying decision to act is wise — that's a different problem, and no verifier, however fast, will ever answer it for you.
Containment and cost are different problems from correctness. This article was about the two we can put a number on.
Run it yourself
The ratio at the top of this page is reproducible in a terminal, not asserted on a slide. If your numbers for inference energy or sandbox boot time differ from the ones here, rerun the model with yours — the structure of the comparison won't change, only the exact exponent will.
Frequently asked questions
How much more energy does an LLM tool call use than a Hyperlambda dispatch?
Using a worst-case model — SOTA LLM inference plus a sandboxed VM boot to execute the resulting action, compared against a whitelisted Hyperlambda dispatch — the gap is roughly 3.1 × 10⁷, or about seven and a half orders of magnitude, in energy per call. Time comes out around six orders of magnitude.
What does "seven orders of magnitude" mean in this comparison?
It means the LLM-plus-sandbox path consumes on the order of 10,000,000 times more energy for the same already-decided action. It's a statement about the cost of re-interpreting and re-sandboxing a decision on every hop, not a statement about intelligence or capability.
Does reducing coordination overhead reduce AI existential risk?
Only for the specific failure mode where coordination itself was the bottleneck — search, triage, and verification at scale. It does nothing for problems bottlenecked by physical processes, like biology or manufacturing, and it says nothing about whether an agent's underlying goals or authorized actions are correct. Speed and correctness are different axes.
What was the Petrov incident and why does it matter for AI protocol design?
On September 26, 1983, a Soviet early-warning system falsely reported an incoming US missile launch. Lieutenant Colonel Stanislav Petrov judged it a false alarm and didn't escalate it, inside a decision window on the order of a transcontinental ICBM's flight time. It matters here because it's the clearest historical example of the exact failure mode a pinned, out-of-band authorization value is designed to prevent: a technically-valid but ambiguous signal producing an irreversible action with nothing requiring independent corroboration first.
Related reading
- How Hyperlambda Saved the World from the Paperclip Apocalypse
- How I Use Whitelist to Execute Partially Untrusted Hyperlambda Safely
- Zero Hallucination Code Generation: A Vocabulary Your AI Cannot Escape
- The Only Sandbox Your AI Agent Cannot Break Out Of